Chatbot-as-a-Service
ChatCraft
I built ChatCraft around a practical question: how can a team ask useful questions of its own knowledge without rebuilding the retrieval and deployment path each time?
View source on GitHubContext
Problem, constraints, and my role
Teams need answers grounded in their own knowledge without repeatedly rebuilding retrieval and deployment infrastructure.
Constraints
- Answers needed to stay grounded in retrieved context.
- Vector indexing and semantic search had to work as one coherent path.
- The application needed a repeatable containerized delivery workflow.
My role
I developed the RAG application and optimized its embedding, vector-indexing, and semantic-search flows.
Project media
The system in view
Interface studies and working demonstrations from the project.

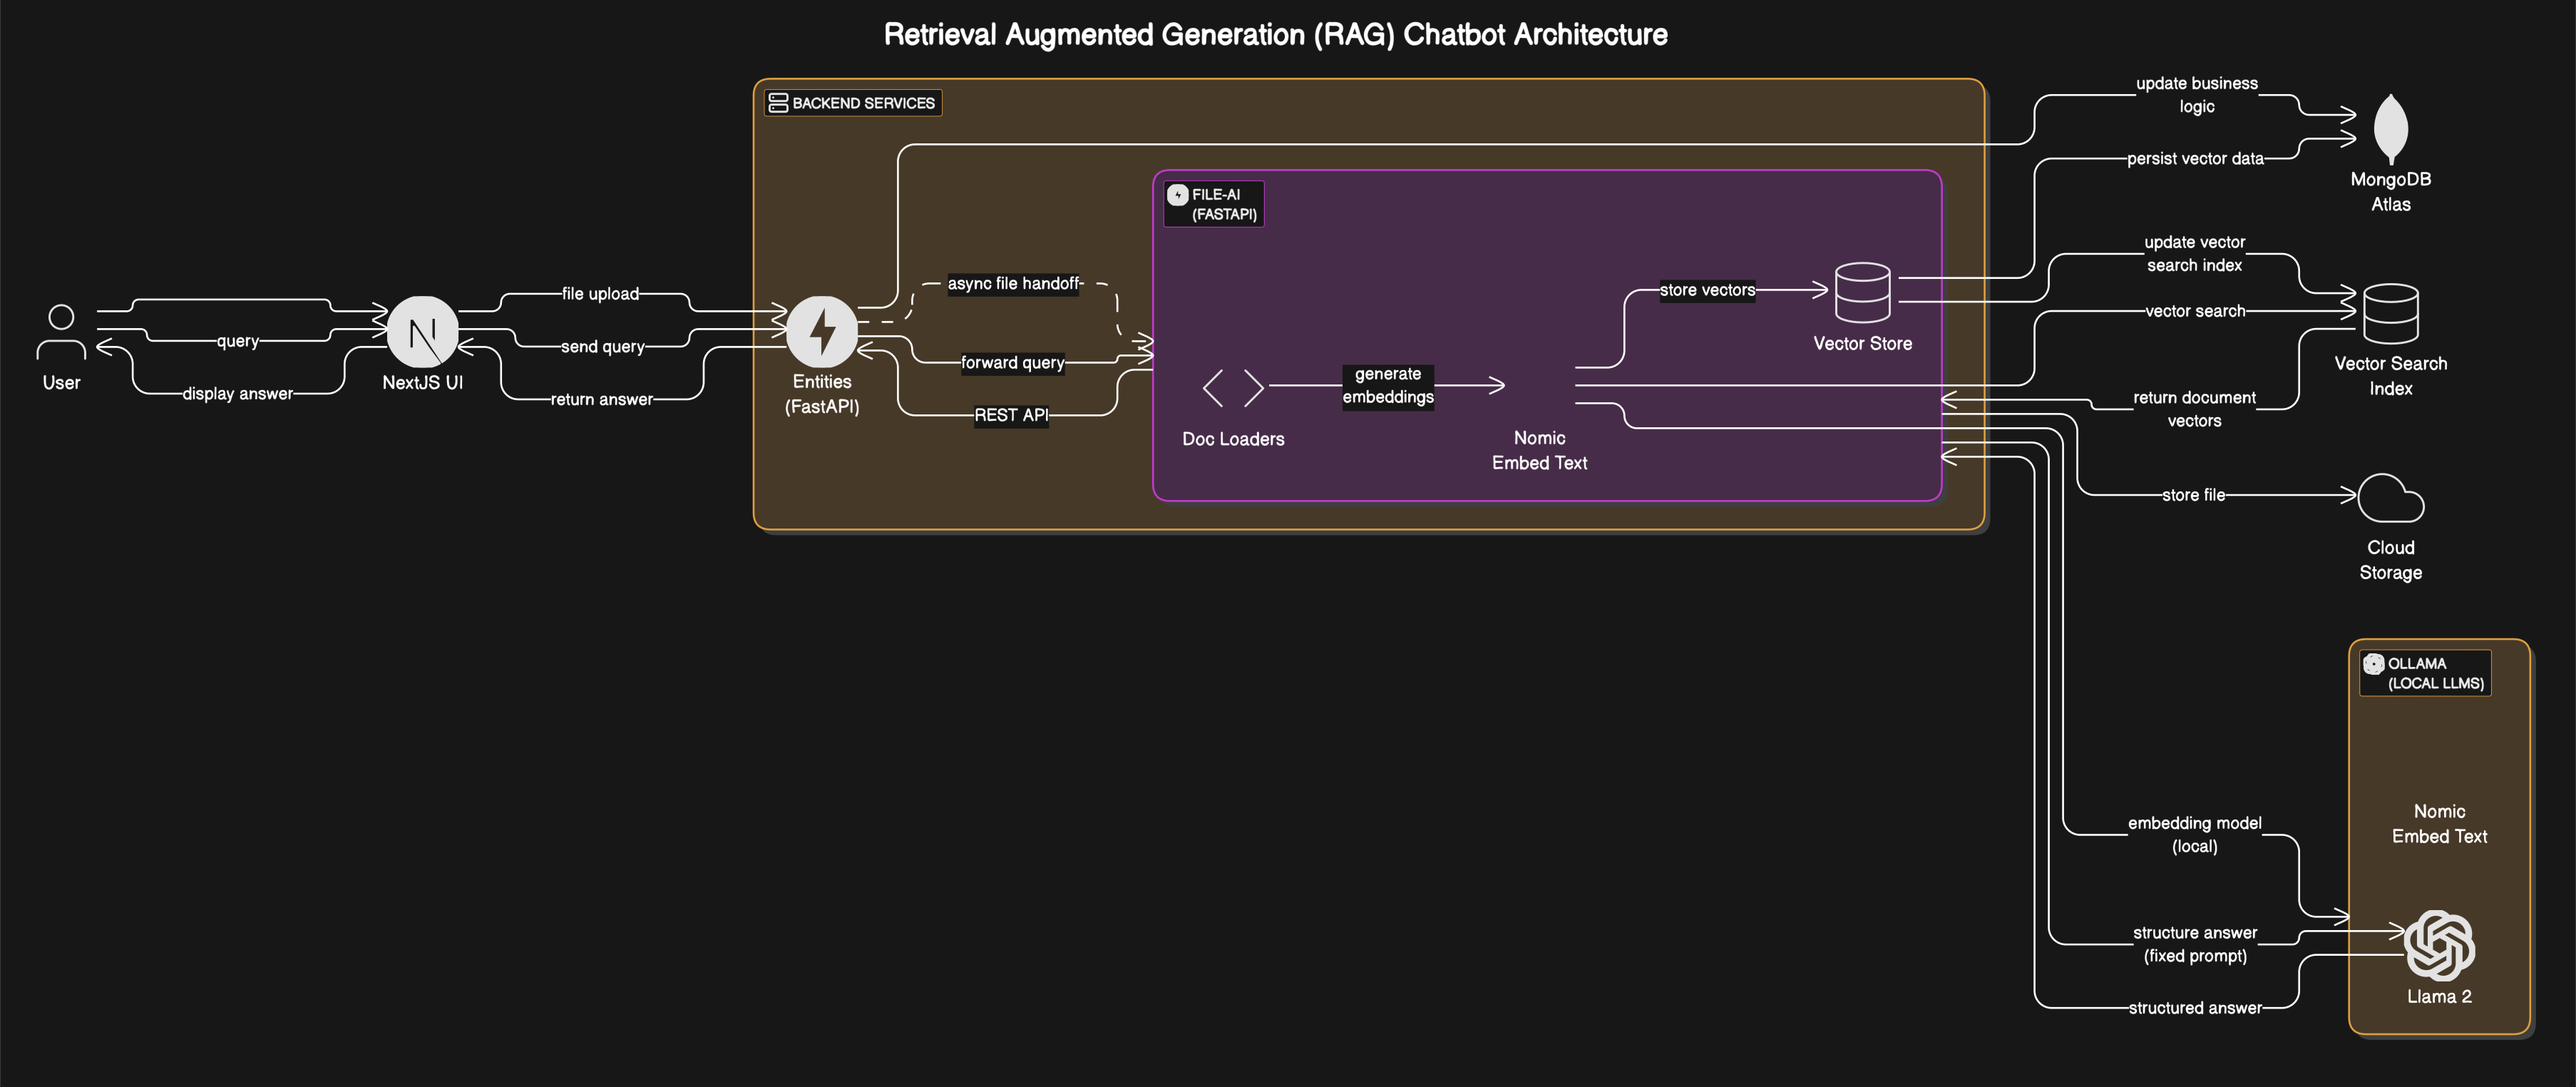
Architecture note
Retrieval and response path
FastAPI coordinates LangChain retrieval, Pinecone vector search, OpenAI generation, PostgreSQL persistence, and Dockerized delivery.
Engineering decisions
The choices that shaped the work
Ground generation in retrieval
LangChain and Pinecone keep the answer path connected to indexed knowledge rather than relying on generation alone.
Treat search quality as product quality
Embedding, indexing, and semantic-search flows were optimized together, because each affects the context that reaches the model.
Make delivery repeatable
Dockerized delivery gave the application a consistent deployment path and helped reduce deployment failures.
Result & reflection
What the work produced
Reached 90%+ context accuracy and reduced deployment failures by 40%.
What stayed with me
This project sharpened my focus on retrieval quality, semantic search, and repeatable delivery as parts of the same product experience.
- FastAPI
- LangChain
- OpenAI
- Pinecone
- PostgreSQL
- Docker